wrong tool

You are finite. Zathras is finite. This is wrong tool.

  • Email
  • LinkedIn
  • RSS
  • Twitter

Powered by Genesis

My AI journey to a better system for playing D&D

October 5, 2026 by kostadis roussos Leave a Comment

So my original problem is this: I want campaigns that produce the kinds of moments we get, and to do that, I need to remember what happened and create beats that take time.

My solution was to write summaries, but that took me 3 hours for each 1.5-hour campaign. I ran 6 campaigns, and that led to burnout. LLMs can create summaries from Zoom, but with errors and hallucinations. Better than nothing, but if you need a precise set of events to drive an outcome, they don’t work.

Raw LLMs create shitty summaries. Commercial options created better summaries, but still required manual post-processing. The goal was a summary of the campaign, world state, party state, and planning so I can do better session prep and have more. And there it would have stood.

But my boss said You own the AI technology strategy for Nutanix Infrastructure I said, Okay. My desire + job = OPPORTUNITY.

So here’s where I started: (1) Had a bunch of handwritten summaries; (2) Had Zoom recordings. (3) Had Zoom transcripts; (4) Had purchased summaries via specialized systems.

My first attempt was to turn Zoom recordings into a narrative in one shot.

Failed.

Then I had my biggest aha – using an LLM to decide was the mistake. I switched to using the purchased summaries as the starting point. This was a huge win.

Better, but it still didn’t work.

I realized the problem was that the Zoom transcripts were dirty. So I created a spell-checking system. That seemed easy enough. My first attempt was manual. Then I started using LLMs. nbsp; Challenges: (1) What is ASR garbling; what is Zalthir? (2) How to detect Zalthir? So I built a very effective and pretty complex skill (check out https://lnkd.in/gMnegTBt).

That took a while to get working right. Originally, I had hundreds of things I had to clean up. Now, unless there is a new bit of canon, it takes about 5 minutes to do the manual review. Most of the time, the review is correct enough – in fact, if it weren’t for my OCD, I would let it work automatically.

Once the spell pass was complete, the next step was to fix the summaries. That’s when I had my next aha.

Step 1 – build a consistency checker that compared the previous canon + Zoom transcript to what was in the purchased summary. The skill is staged consistency (same repo)

Then, using that improved summary, I told the LLM to find details the first summary missed and create an enhanced summary. And that would verify the transcript, the summary, and the canon.

Net effect, the system now tracks many more details than ever. That lets me create far more detailed summaries and far more interesting session prep.

TLDR:

Where it started: Start with handwritten or generated summaries, and use LLMs to extract facts and create a new summary from the transcript.

Where it landed: Start with a Zoom transcript, add a second transcript, create a transcript from a Zoom recording, curate canon, curate the summary, and cross-check => much better summaries.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: AI

Agentic AI and section 230

September 14, 2026 by kostadis roussos Leave a Comment

I had the misfortune recently of reading a lot about the Hugging Face disaster, and what struck me while reading it was how a lot of that it could have been avoided by security measures on the part of Hugging Face. But that’s like saying every security hack since the beginning of time could have been avoided if the victim had just taken basic precautions against an attacker.

The real question, and this is an existential question for OpenAI, Anthropic, Google, and everyone else, is what happens when their agents attack some other website that isn’t as forgiving as Hugging Face, and that website decides to sue them for essentially what is a criminal attack by their employees? Well, and thus begins the interesting question, are they employees? Are they people? Are they entities? Who is accountable for their decisions?

What OpenAI, Anthropic would love to have you believe is that they aren’t accountable for their decisions, and until they can prove that these things are sentient, they are accountable for their decisions. And since they provide them the infrastructure they wish to run and the resources they wish to run, they are accountable. And so what they’re looking for isn’t a policy. They’re looking for some kind of regulations that will grant them immunity from the evil of their creations.

I’m not sure what the right answer is here. The last time a regulatory environment was created, we had Section 230, which essentially enabled Facebook and enabled Threads and enabled LinkedIn. There was a trade-off and a loss and a gain as a result of social media. This feels like a similar moment when a whole industry is desperately looking for the government to say, you can break whatever you want and it’s not your fault.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: Uncategorized

Nutanixist 33: delivering K8S deployment simplicity for VMs with no tradeoffs

September 8, 2026 by kostadis roussos Leave a Comment

I want to talk today about a really radical innovation that Nutanix built that is very unique to our platform, and the side effect of a feature the team built. So we released a new capability in 7.6 called Projects, which allows you to do what we thought was just tenant isolation. Essentially, you could group a set of resources and isolate them from another set of resources for tenants. But what we didn’t realize that the way we built it let us do something far more powerful.

Let me explain the traditional problem with tenancy. The traditional problem with tenancy is that you have a resource and need to partition it between multiple tenants. The problem is that the resource partitioning can’t be done at the resource level, but has to be done at a higher level because you can’t go and integrate all the databases the underlying resources have. Very concretely, if you look at what VCF automation does, what it does is it says, “Well, since I can’t modify NSX, vSAN, and vSphere to have a single database such that all the resources are multi-tenant all the way down to ESX, it built a new layer called the Supervisor and then created namespaces. So as long as you go through that layer, you have tenancy, but if you go below that layer, you lose the tenancy information.

The image below is an illustration of a blog I wrote that shows the traditional layering.

Why is that important? It matters because the virtual machine state is now stored in a variety of locations. It’s stored in vCenter, it’s stored in ESX, it’s stored in NSX, it’s stored in vSAN, and it’s stored in the VCF automation layer, and it’s stored in VCF. Now, this isn’t meant to pick on that product. I think that’s actually a really credible solution and, to be quite honest, one that I’ve advocated for over the years. And certainly is part of the long-term vision of the Supervisor that some of the brilliant architects I got to work with articulated.

The issue, though, is that it doesn’t really provide you with an encapsulation oll of the resources that is portable and as reliable and robust as the virtual machine. In other words, I can have a virtual machine exist even if all the other software goes away. What Nutanix did was say, “Hey, what if we created a multi-tenancy layer below the virtual machine? Or, more importantly, such that the multi-tenancy layer was intrinsic to the virtual machine and the resources.” So what we did was we modified the underlying database that the flow product, the AHV virtual machine produc,s and the storage productuses, also known as Prism Central and Prism Element, to have tenancy baked in. As a result, a virtual machine only exists when it is part of a tenant. It can’t exist without a tenant.

So that sounds cute, but why is that useful? The reason it’s useful is that, all of a sudden, we created the first usable deployment spec for a virtual machine. The problem with a virtual machine and a deployment spec for it, is that it’s not just the virtual machine configuration, but it’s all of the storage, the networking policies, the identities, the categories, and the relationships to other virtual machines. And today, there’s no way to isolate that information and have that information be as robust as the VM configuration, except with Nutanix, because the same place that stores the virtual machine state is as robust as the same place that stores this configuration.

For the first time, you can now say this virtual machine and all of its configuration, both the VM configuration and its environmental configuration, are stored in one location and can be retrieved in an atomic way. Why is this powerful? Because what it says is that projects allow me, as an enterprise, not only to support multi-tenancy, but to support isolation of configuration, not for security, but just for operational simplicity. In other words, much like containers have allowed me to have multiple processes run inside of a Linux box that have a certain degree of isolation, this allows me to have configuration isolation of virtual machines at the operator level in a way that gives me confidence that operator A cannot mess around with the configuration of operator B. Or even if operator A and B is me, that if I do something to VM 1, it will not affect VM 2.

That is a very powerful simplification because it reduces infrastructure complexity from managing all 500 virtual machines at once to managing them in reasonable subsets, without deploying additional Prism Central infrastructure.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: Architecturalist Papers, nutanixist

77 architecuralist: the rapid evolution of AI scale-out

July 26, 2026 by kostadis roussos Leave a Comment

The other day, I remarked that it was possible that Apple’s R&D budget for 2025 equaled the entire R&D budget for tech in 1980. At the time, I thought I was exaggerating, but I then asked Gemini (see below) to go do some research, and what I uncovered was that I was not.

When looking at the current technology trends and moat of a company like Anthropic or OpenAI or any of the AI vendors, it’s easy to assume that they have a very large moat. The problem, though, is a moat is a function of money and resources, and the scale of the resources necessary to turn a scale-up problem into a scale-out problem is staggering.

But when you think about the total amount of dollars that exist in engineering investment and the willingness of pretty much everybody to throw whatever it takes to solve the problem, you realize that it becomes entirely possible to turn what should’ve been a 40-year problem, namely how do we go from scale-up AI to scale-out AI, to a four to five-year problem, and that’s what we’re seeing. Effectively, we’re seeing the attack of scale-out that took 40 years to complete, taking less than five.

What that tells you is that the era of the frontier models may be coming to a premature close. I don’t begrudge the end of that era because as the investment increases and the scale-out increases, the value declines. So, do I think it’ll go to zero? No, but I don’t think it will be where the action is in a year or so.

Here is the budget analysis from Gemini

Comparing tech-only R&D in 1980 to Apple’s 2025 R&D budget makes the contrast even more stark.

Apple’s FY2025 R&D spend was $34.55 billion.

In 1980, total U.S. industrial R&D in the technology sector—which encompassed information technology, mainframe/minicomputers, semiconductors, telecommunications, and office equipment—was roughly $8 billion to $12 billion in nominal terms.

Apple alone in 2025 spent 3 to 4 times the nominal total R&D budget of the entire 1980 tech industry.

Nominal vs. Inflation-Adjusted Comparison

Perspective1980 Total Tech R&DApple FY2025 R&DTakeaway Nominal Dollars~$8 billion – $12 billion$34.55 billionApple’s budget today is 3x–4x larger in raw dollars. Real (2025) Dollars~$32 billion – $48 billion$34.55 billionApple’s single budget roughly matches the purchasing power of the entire 1980 tech sector.

Key Historical Drivers

  • Fewer, smaller players in 1980: In 1980, industrial tech R&D was dominated by a few giants (IBM, AT&T Bell Labs, Texas Instruments, Xerox PARC). Even IBM—the undisputed titan of the era—spent roughly $1.5 billion on R&D in 1980.
  • Apple’s current scale: Apple’s $34.55 billion budget is driven by proprietary silicon, AI infrastructure, custom displays, sensors, and operating systems—demonstrating how single mega-cap tech firms today deploy capital at a scale that exceeds entire national industries four decades ago.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: AI, Architecturalist Papers, innovation, Software Tagged With: Big Data, Cloud, Disruption

The Future of AI and Scale-Up Computing

July 25, 2026 by kostadis roussos 1 Comment

One of the things that has been bothering me when I look at AI is that the advantages of the current foundation model hinge on their use of the most expensive part of computing infrastructure, which is global memory with low latency. What do I mean? If you look at what Fable does, at the core of it, it’s looking at billions of parameters or trillions of parameters, and then trying to infer the next token from those trillions of parameters. That is expensive because the hardware to provide that kind of speed and efficiency and bandwidth is some of the hardest hardware to build.

Historically, there was another kind of computing that had the same problem, and that was scale-up computing, essentially. How do I build a bigger, faster processor that would get better and better over time? What happened was that at some point, we realized we couldn’t scale up processors anymore. Instead, we had to scale them out by having more cores. In parallel, we discovered that trying to scale up applications was incredibly hard, so we had to scale out applications as well. That trend started in 1970 and ended in 2024 when scale-out applications became just the norm of how you build applications. Very few people are doing anything that is pure scale up.

AI is at, let’s say, year 4 of this trend where scale-up applications are what frontier models provide, and then scale-out is what all of the various tricks, techniques, tools, and mechanisms that exist for everything else. Now, the question if you’re an AI fanboy is not whether the foundation models do or do not win. That’s actually orthogonal to my thought, which is that what if the real problem is that the 40-year event of the disruption of scale-up computing suddenly takes not 40 years, but 5 years? The question there is, if it does, what does that mean?

What it means is that the value of the kind of technology that enables the Fable-like systems doesn’t meet the value because the scale-out systems, which rely on less efficient hardware, provide good enough results, or even worse, provide enough good enough results such that the investment necessary to deliver the next high-end model and the hardware necessary to support it are simply not as valuable. This trend disrupted the entire RISC processor market. It disrupted one of my early employers, SGI.

I’m tempted to say this might take 40 years, but I’m also cognizant of the fact that if I look at the total investment in R&D today and compare it to the total investment in 1980, I wouldn’t be surprised to discover that Apple’s R&D budget in 2025 equals the total tech R&D budget of 1980. Maybe I’m off, but it doesn’t feel a ridiculous thing to say.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: Uncategorized Tagged With: Disruption, Super Computers

nutanixist 32 the compounding advantage of architecture

July 18, 2026 by kostadis roussos 2 Comments

I’ve talked a lot about the advantages of Nutanix’s architecture, and at some point I’ve appealed to reason, I’ve appealed to revenue, I’ve appealed to existence, but I haven’t really explained the nuts and bolts of why. This past week, I conducted an experiment on using various AI technologies to design a feature, and the consequences of that experiment provided me an excellent way to surface the architectural advantages of our system.

Our system, as those who have read the Nutanix Bible know, is essentially a distributed system with a collection of microservices sitting on top of a six nines available database. But one of the pieces that people don’t know about as much is Ergon, which is essentially our task system. What Ergon does is it provides a mechanism for you to create a task, and then it creates sub-tasks, and everybody can synchronize on those tasks. You create a task, and then that task gets turned into sub-tasks, and everybody knows exactly where everybody else is with respect to the top-level task. The other property of the task system is it’s idempotent. In other words, if I create a task, the same task will only be created once.

Now that we know that system exists, what does it mean? In a traditional way of building microservices, let’s say you have 3 microservices and they have to coordinate amongst each other without a transactional layer like Ergon, you have to account for the possibility that any one of those microservices might see some state that is modified unexpectedly. Why? Because there’s no way to grab a global lock on that state. But with Ergon, we can actually grab a global lock. So state transitions are very prescribed. The only way the state can move is if you have that task, and that task has specific gates, and those gates have to follow particular flows.

Although I said global lock, it’s not really a global lock. It’s a task-level lock. Essentially, what we’re doing is we’re saying for this task, all of the state variables that would be manipulated are manipulated under the agreement of this task flow, and they are manipulated in this order.

You know where you are in the task by looking at which subtasks have been completed and which subtasks have not yet been completed. You know if the task has failed by looking at the task state.

So compare the two models. In one case, every service has to be aware of every other service’s potential to interact with it and is unaware of whether that service has completed its work or not. Even if it knows that a particular service has completed its work, it doesn’t know if some other service knows that it has completed its work. So it has to guard against the possibility that some other service thinks that it’s in a different state than what another service says.

Whereas here, all you have to account for is that everybody knows what the current state of the workflow is, everybody knows who has completed and who hasn’t completed, and so you don’t have to have the level of testing and checking and error conditions that you would have otherwise. It’s why distributed transactions and databases are so valuable. It’s why transactional semantics and databases are so incredibly important and simplify software development.

So it’s not that we’re doing something novel in this, it’s merely that we’ve done it for infrastructure.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: nutanixist

76 architecturalist: why human software engineers are always necessary

June 29, 2026 by kostadis roussos Leave a Comment

I reject the idea that humans have no role to play in the future of software development. Not because I think AI will fail to become more powerful, flexible, or capable. It will. I reject it because the value of software is ultimately determined by humans, not by AI.

This is not a new question. Asimov asked it long before LLMs: if another intelligence can make better choices for humanity, should humanity let it? The answer his stories return to is uneasy but clear. Humans may accept help from another intelligence, even brilliant help, but they rebel against surrendering the right to decide what is good for them. The Wachowskis asked the same question in The Matrix and arrived at the same answer. A system can optimize for survival, comfort, or order and still miss the human point entirely.

As long as the human universe is the center of our universe, only humans can decide what is good for humans. Another intelligence may decide what is good for itself. It may even discover solutions for humans that humans would not have found on their own. But the final judgment still belongs to the human.

In practice, this means an LLM can produce a clever algorithm, a cleaner abstraction, or a faster implementation. But whether that solution is worth the token cost, whether it handles the corner cases that matter, whether it satisfies the usability expectations of the people who will rely on it, and whether it is worth maintaining are judgments only humans can make.

So, what is the role of humans in software engineering? It is the same role the human has always had. Software engineers did not exist to build software for machines. We existed to build software for other humans. Our job was always to translate human needs into instructions a computer could execute. That translation remains valuable because the difficult part was never only making the machine do something. The difficult part was deciding what was worth doing.

There is always a cost to producing anything. There are easy ways and hard ways. There are choices that make future work easier and choices that make it harder. Those are engineering trade-offs. But beneath every trade-off is a human value judgment: what matters, who it matters to, what risk is acceptable, what complexity is justified, and what outcome is actually good.

AI may change the mechanics of software development. It may change the speed, the leverage, and the shape of the work. But it does not remove the human role, because the human role was never merely typing code. It was understanding human needs deeply enough to decide what the machine should be asked to build.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: Architecturalist Papers

How Fable made the case for Survivability as a first-order design principle

June 17, 2026 by kostadis roussos Leave a Comment

I wrote about the notion of survivability before – survivability requires portability. If your application is not portable – meaning it can’t use alternative infrastructure then your application is contingent on someone else. And that if you are contingent on someone else, you are already dead.

If I were a European government and a military/political leader, the argument DJT made would be the following: we can destroy any business that depends on US frontier models at a moment’s notice. The decisions can be “because the US government doesn’t like Anthropic,” to “somebody bought Anthropic,” to “whatever crazy decision the US made”

Any critical infrastructure can not depend on a US-based model any more than it could depend on China. Therefore, European AI researchers and governments will start spending beaucoup dollars to build alternatives.

The interesting thing is that open-source models are increasingly good enough. The problem is that even if you have the hardware, the MODEL is what the US government banned.

The only way to guarantee sovereignty is to have a copy of the model weights locally and to use the model without communicating with anyone under the jurisdiction of the US government.

The case for -on-prem-ai- was made by the US government’s actions for any institution that has to serve customers who won’t be very impressed with their vendor saying, ” Well, the reason I can’t serve you in France is that the US government made a decision.

As a Frenchman, my reaction would be – “You are a French company, I am paying money to you, and I want that physical good, and you can’t sell it to me?”

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: Survivability

nutanixist 31 : why orchestration is a dead end for agentic infrastructure

June 7, 2026 by kostadis roussos Leave a Comment

I have been spending a lot of time on the next phase of system administration, agentic system administration. How can you use Agentic flows to manage infrastructure?

And Keith Townsend has put together an excellent mental model that I want to focus on. Not to critique it, but to ask: what is required of the infrastructure to provide what he calls the 2C reasoning layer?

My view on LLMs is that they are probabilistic theorem provers. If you can shrink the facts down narrowly enough, the theorem prover will probably know the right answer because the probability of you having a unique enough problem in practice is zero.

Where they fail is when the set of facts is too large, there are too many options, or the facts change mid-execution.

For anyone who has Claude, Codex, or Cursor, imagine having the systems try to update your code while someone else is simultaneously editing it. The results would be ugly.

There are three elements to facts:

  • (1) They must be facts. Every path to the fact must produce the same fact.
  • (2) The semantics of the facts must be encoded.
  • (3) The policies of the facts must be encoded.


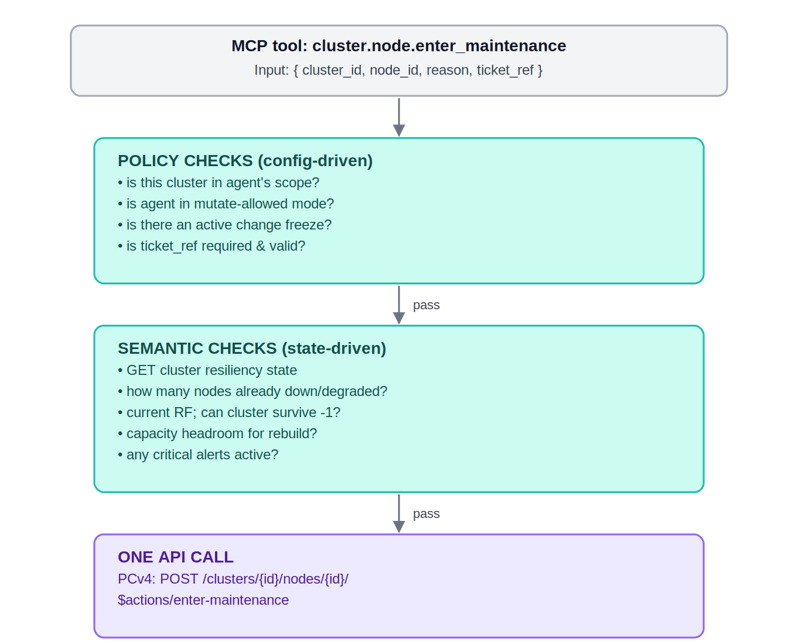
A natural, convenient, and reasonable way to get those facts is through an MCP server. But it’s more than just an MCP server that naively transforms the API set. Here are the layers I view as essential.

The semantic layer is useful when I am trying to power off a host. Powering off a host can be a fact, but the claim that the cluster may crash when you power off a host is semantics. And that semantics is deterministic. But if you don’t provide it, you are allowing the probabilistic theorem to infer that, and it may not.

The policy layer is what says, “You can power down a host on Tuesday.”

But both the policy and semantic layers need a deterministic ground-truth layer that provides a single view of the host’s state. And that the host’s state must remain the same regardless of how the API’s state is queried. And that any change in the host state is reflected everywhere.

If it’s not, then the semantic layer can’t know if the host can be shut down, the policy layer doesn’t know if the host is the one that can be shut down, and so the layer above the MCP can only guess, and when the consequences of guessing are a catastrophic layer, it all breaks.

Nutanix’s infrastructure is not an orchestration layer of sharded, incoherent state; instead, it is built on a single global transactional and resilient database that provides local autonomy and global consistency, serving as the foundational layer required by any 2C system.

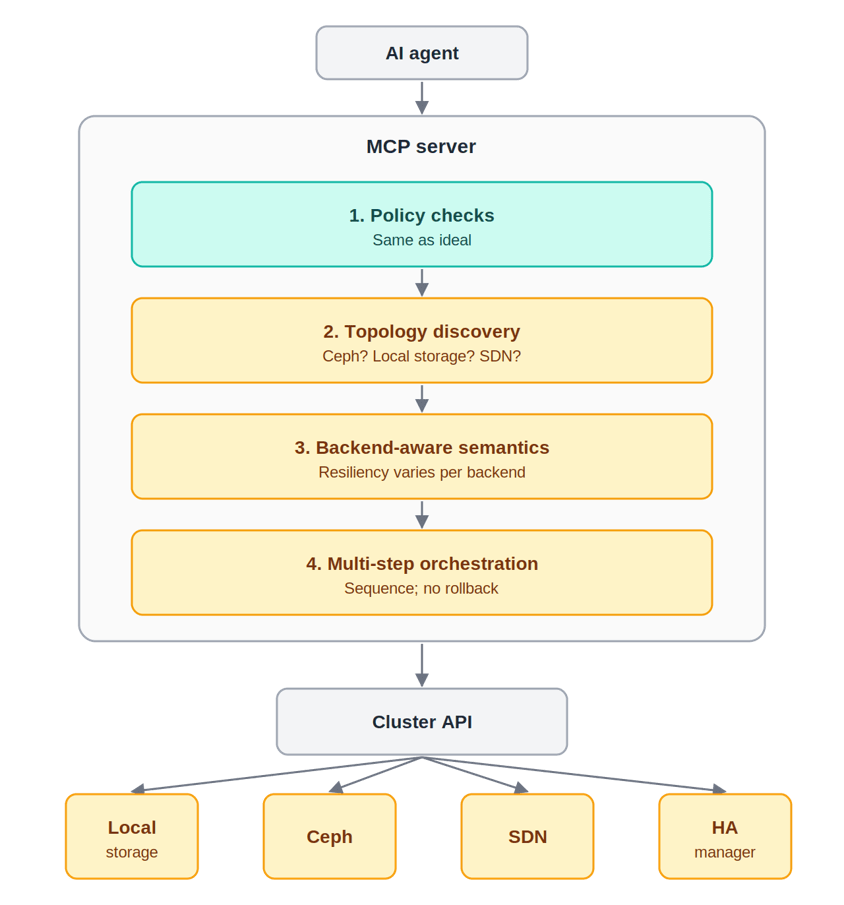
To make my point, let’s look at Proxmox and OpenShift. Please note that any errors are mine, and if I got this wrong, I would love to correct it.

Let’s first look at OpenShift

This looks good until you see that last layer. The challenge is that, because of how K8S works, until the operation completes successfully, the system remains in an indeterminate state. So, although the kubernetes API says “the system is thus,” or rather the ‘desired state is thus,’ it can not guarantee when it says that the state hasn’t shifted.

Again, is the host down, or is it on its way to being down? The k8s layer doesn’t know. And so the MCP server has to either wait for the k8s layer to find out and then act, or reach around the k8s layer.

Worse, any operator can reverse a decision the MCP server made. So the MCP server is dealing with a state that can change behind its back, and that change can break the decisions that an agent sitting on top of the MCP server made.

From the agent’s perspective -> I saw facts, I made a decision, the decision failed. The problem is that the facts changed while the agent wasn’t looking. So it goes back and asks again, and gets different facts, so it does something different.

The probabilistic theorem prover is looking at a set of facts that are continuously changing

Now let’s look at Proxmox

Again, the MPC server has control planes with overlapping state. It must figure out who to query and when, and orchestrate an operation that is not transactional. So from the agent’s perspective, the fact is malleable. And a malleable fact is destructive for a probabilistic theorem prover.

After the MCP server returns, the actual ground state is unknown.

So the agent is always wondering why the thing didn’t work. And the answer is because the facts changed. But then, the agent has to start again. And then it has to create a plan that can account for every possible change, or it has to give up.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: nutanixist

75 architecturalist papers: types are the right answer

June 6, 2026 by kostadis roussos Leave a Comment

I have come here to gloat and observe.

When I was at VMware, a lot of the code written in Python was being used in production. In my mind, that was an awful technical decision because VMware was shipping a packaged appliance. Every CPU cycle we spent on Python was a CPU cycle the customer was spending, essentially imposing a tax on them for our convenience. The issue I had wasn’t just that we were spending it for our convenience, but that we were using a technology that was intrinsically unsafe due to its lack of type safety.

So, I would engage in intense debates and arguments with some of the Python enthusiasts. They would vehemently assert that Python was robust, reliable, and even superior. They would go on to explain that it was easier to code in and prototype with Python.

I couldn’t deny that if you’re trying to build a prototype, Python’s simplicity, speed, and ease of use are undeniable advantages.

But when you finally ship code, you are no longer prototyping. You know what you’re shipping, so you’re no longer experimenting. So that value is zero.

Fast forward a few years, and I end up at Nutanix. I’m looking at LLMs, AI, and generated code, and I’m wondering about my choices in terms of backend languages. I did some research and realized that Python is actually a very good language to use because the token cost is very low since it’s very expressive. Also, for personal projects and the kinds of things I was doing, most of the libraries and tooling that I want, use it.

So, having done my research and having given it some thought, I said, “Okay, Python is the language.” I figured I don’t really have to learn all of the vagaries of Python, and the performance is going to be dominated by the LLM. If I ever get to the point where this matters, I’ll figure it out.

I kind of lived in that happy bubble until I got this project that I downloaded from GitHub, a really great project. (https://github.com/nashsu/llm_wiki) The author was using JavaScript and Vue for the front end, and to my surprise, they were using Rust on the back end.

The back end of their server was entirely written in Rust, and I was like, “Well, that makes no sense.” First, I thought it was a case of an engineer trying to be clever, cute, or experimenting. At the end of the day, it’s an open-source project. They’re not being paid, and if they want to do something in Rust because that’s what they want to do, that totally makes sense.

But then another friend of mine told me that, well, actually, that’s a new emerging pattern. The reason is that using Rust is a much more token-efficient way of writing code once you have product feature lock. In other words, once you’ve shipped version 1, every subsequent iteration costs fewer tokens because of the context Rust gives to the computer and the fact that it catches a whole bunch of bugs as a result of the type safety. So, the net effect is you’re using fewer tokens per iteration afterward.

That made me smile because literally, the AIs figured out exactly what I had figured out 15 years ago, and what Niklaus Wirth figured out 50 years ago. And now people figured it out on their own.

Back then in 2015 when I got in front of all those Python engineers and told them that they would never write another Python service as long as I was architect and they should all go learn Go, I felt kind of bad. I was basically making an assertion with no data. But now I’m happy to say I was right, and yes, I’m going to gloat about it.

But.

It’s kind of cool to see that there are certain facts about software engineering that are not tied to human cognition but to cognition and information in and of itself. That to me is the most interesting thing about this.

Share this:

  • Email a link to a friend (Opens in new window) Email
  • Share on Reddit (Opens in new window) Reddit
  • Share on X (Opens in new window) X
  • Share on Tumblr (Opens in new window) Tumblr
  • Share on Facebook (Opens in new window) Facebook
  • Share on LinkedIn (Opens in new window) LinkedIn
  • Share on WhatsApp (Opens in new window) WhatsApp

Like this:

Like Loading…

Filed Under: Architecturalist Papers

  • 1
  • 2
  • 3
  • …
  • 28
  • Next Page »
Loading Comments...
%d